EDAG: Evolutionary DAG Search for Neural Mechanism Discovery
A graph genome, three kinds of wires, and a quality-diversity archive that lets memory and recurrence evolve rather than be designed.
In brief
EDAG evolves neural networks encoded as typed directed graphs, where feed-forward edges must form a valid DAG but separate state and recurrent edges are allowed to form loops, so memory and feedback are evolvable graph objects rather than hand-designed cell types. A steady-state, age-based evolutionary loop mutates and recombines these genomes, selecting on fitness plus a behavioral-novelty bonus while a MAP-Elites archive binned on depth and statefulness keeps diverse high-quality solutions alive and supplies parents. Weight inheritance and staged training make evaluation affordable and protect young mechanisms, and a macro-mining step promotes recurring subgraphs and memory update rules into reusable building blocks, giving the search an open-ended, self-expanding operator set. The engine is implemented in both Python and Rust and exports the discovered model to TorchScript.
Key results
- The same search, unchanged, is run from a minimal modality-appropriate seed (a small conv stem for image inputs; population 10, 40 steps, staged budgets, AdamW lr 1e-3) on four image-classification benchmarks of rising difficulty: it reaches validation accuracy 0.995 on MNIST, 0.943 on KMNIST, 0.865 on FashionMNIST, and 0.662 on color CIFAR-10, filling 4-13 MAP-Elites cells and promoting macros on every run. The best genomes grow and rewire the seed and several carry memory cells joined by a recurrent edge.
- Implemented twice against one libtorch backend - Python over PyTorch and Rust over tch-rs (graphs on petgraph) - with a deterministic batched evaluation order, a cross-language interop test that runs a Python-written genome in the Rust engine, and a container path: a multi-stage Dockerfile that bundles libtorch and the datasets, plus a Kubernetes deployment and service.
- Genomes are networkx DiGraphs with three edge kinds (ff, state, recurrent); is_valid() requires only the ff-subgraph to be a DAG with an input-output path, so state/recurrent loops are legal and let recurrence and memory be first-class evolvable structure rather than fixed cell types.
- DynamicGenomeModel compiles any valid genome by topologically sorting the ff subgraph, running every node in a shared internal_dim=32 latent space, and auto-selecting conv / sequence / graph / flat input adapters purely from which NodeTypes are present.
- MEMORY_CELL nodes hold a persistent hidden state with three selectable update rules parsed from the gene's update_rule string - a single Linear+Tanh update ('standard'), an exponential moving average ('ema<alpha>'), or a GRU-style gate ('gru') - and whether state is written at eval time is a configurable toggle (state_updates_in_eval).
- The mutation operator is a weighted mix: add_connection 0.35, add_node 0.22, tweak 0.13, remove_node 0.10, plus two mechanism operators add_memory 0.10 (inserts a memory cell with a state write-edge and an ff read-edge) and add_recurrence 0.10 (adds a recurrent feedback edge).
- Search is steady-state regularized evolution: children are ranked by fitness + novelty_weight (default 0.25) * novelty, where novelty is a behavioral descriptor read from the run (the mean and standard deviation of the output logits, the norm of a one-step parameter update, and the change in memory state); parents are drawn from both a size-three tournament and the quality-diversity archive, and the oldest individual is always evicted to keep the population churning.
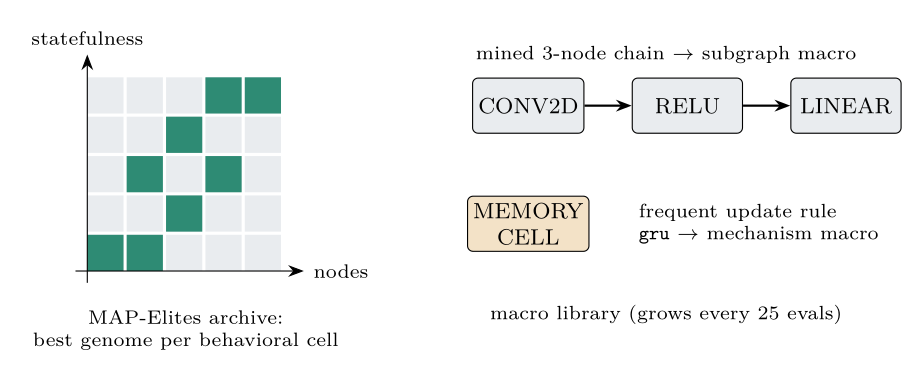
- A MAP-Elites archive bins genomes by a depth proxy (nodes//3) and a combined statefulness-plus-edge-density proxy ((stateful + edges//5)//2), both clamped to 0-9, and supplies parents alongside tournament selection, while mine_macros extracts recurring 2-, 3-, and 4-edge node-type chains and common memory update rules from evaluated genomes and promotes them into a splice-in macro library, letting the search grow its own operator set.
The motivating question
The system's specification is explicit that a search over permutations of known layers is not enough. Reordering blocks, swapping activations, and tuning widths cannot produce the kind of paradigm shift represented by test-time memory or nested optimization; those require new computational behaviors, not new wiring of old ones. EDAG's stated design goal is therefore mechanism discovery: architectures that carry persistent internal state, define explicit rules for how that state evolves, behave differently at training and inference time, and can invent and reuse their own abstractions.
That reframing drives every concrete choice in the code. A candidate is treated as a stateful computational program rather than a pure forward function, and structure, internal state, and state-update logic are kept as separate, independently mutable dimensions. The practical consequence is a genome representation in which memory and feedback are ordinary graph elements that mutation can add, not privileged primitives supplied by a human.
Genome and compiler
A genome is a networkx directed graph of NodeGene objects. Node types span the usual families - CONV2D, MAXPOOL2D, LINEAR, RELU, BATCH_NORM, DROPOUT, ATTENTION, LAYER_NORM, LSTM, EMBEDDING, MESSAGE_PASS, RESIDUAL_ADD, FLATTEN, TOKENIZE - alongside the mechanism extensions MEMORY_CELL and RECURRENT. Crucially, edges are typed: 'ff' (feed-forward), 'state', and 'recurrent'. Validity is checked against the ff-only subgraph: it must be a DAG and contain at least one path from an input node to an output node. State and recurrent edges are deliberately excluded from that acyclicity test, so they are permitted to form cycles because they are resolved across timesteps rather than inside one forward pass.
DynamicGenomeModel turns a valid genome into a torch.nn.Module. It topologically sorts the ff subgraph and instantiates one module per node, but every internal node reads and writes a single shared latent width (internal_dim, default 32), which sidesteps shape-matching between arbitrary layer pairs. The compiler inspects the node types once to choose an execution regime - convolutional, sequence, graph, or flat-vector - and installs the corresponding input adapter (for example, unfolding an image into patches for sequence mode, or splitting features from an adjacency block for graph mode). Attention is implemented as explicit q/k/v/o linear projections with scaled softmax; message passing normalizes the adjacency by degree and combines self and neighbor projections; unknown or marker nodes pass their input through. A final output head projects the pooled latent to the class logits.
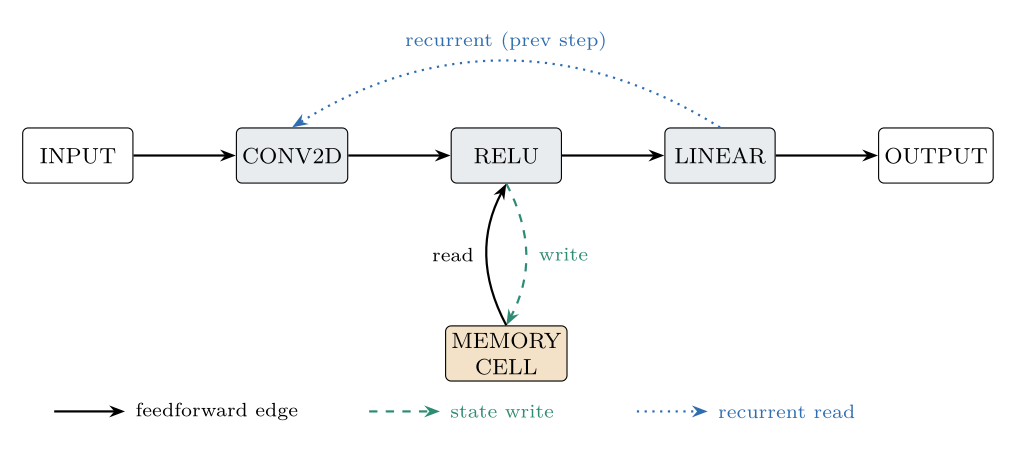
Memory is where the mechanism intent becomes concrete. A MEMORY_CELL keeps a persistent hidden buffer in the module and updates it from its incoming 'state' edges according to an update_rule string carried on the gene: 'standard' is a single nn.Linear(2*dim, dim) followed by a Tanh (one linear layer plus a tanh, not a multi-layer perceptron) over the concatenation of the write input and previous state, 'ema<alpha>' is an exponential moving average, and 'gru' is a GRU-style gated update. Recurrent edges are read from a cache of the previous step's node outputs. Whether these state writes happen during evaluation, rather than only during training, is governed by the state_updates_in_eval flag, so the same genome can behave as a static function or as an adapting, memory-writing program depending on configuration.
Mutation and recombination
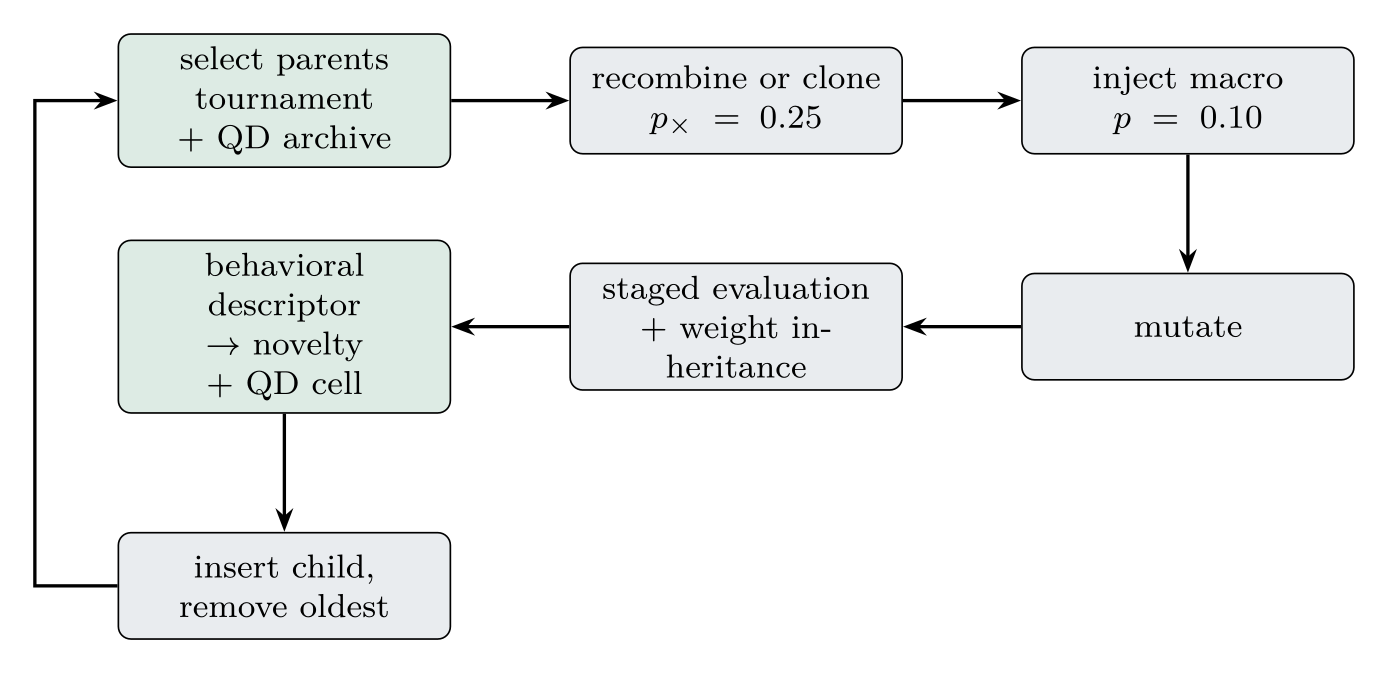
New genomes come mostly from mutation of a single parent. The Mutator applies one operator per call, chosen by a fixed weighted distribution: add_connection (0.35), add_node (0.22), tweak_node (0.13), remove_node (0.10), add_memory (0.10), and add_recurrence (0.10). add_node splits an existing edge and inserts a new node whose type is itself drawn from a weighted menu skewed toward RELU and LINEAR but reaching CONV2D, ATTENTION, LSTM, and MESSAGE_PASS. remove_node deletes a non-IO node and rewires its ff predecessors to its ff successors, and add_connection adds an ff edge only if the result stays valid, undoing itself otherwise.
The two mechanism operators are what let the search jump between model families. add_memory creates a MEMORY_CELL and wires it with two edges of different kinds - a 'state' edge into the cell (the write path) and an 'ff' edge back out (the read path) - so a single mutation introduces genuine persistent state with correct read/write semantics. add_recurrence adds a 'recurrent' edge between two nodes, injecting feedback without violating ff acyclicity. Alongside mutation, a graph crossover recombines two parents by copying one parent's nodes, remapping and merging a random subset of the other's nodes and edges, and repairing to a valid genome (falling back to a clone of the first parent if the merge is invalid). Weight inheritance is attempted on every child: the parent's state_dict is loaded with strict=False so shared modules keep their learned weights and only new modules start fresh.
Evaluation and selection
Each child is trained and scored by an Evaluator that builds the model, does an 80/20 train/validation split of the dataset, and runs AdamW (lr 1e-3) with cross-entropy loss. Training is staged to protect fragile novelty: a short early phase runs first (a few batches), and only if validation accuracy clears a threshold (default 0.12) does the model earn a mid-length phase, and only above a second threshold (default 0.25) does it reach the full-length phase, where it is trained for several passes over the budget. Genomes that fail to compile receive a large negative score rather than crashing the run. The evaluator also emits a behavior descriptor drawn from actual run-time behavior - the mean and standard deviation of the final-batch logits and the L2 norm of the parameter change from one extra optimizer step - plus a memory state-delta signal, so that novelty is judged by how a model behaves, not merely by how it is wired.
The EvolutionEngine runs steady-state, regularized evolution. The selection score is fitness plus novelty_weight (default 0.25) times novelty, where novelty is the sparseness of a candidate's behavior - the average distance to the k=15 nearest neighbors among the current population and an archive of past behaviors - and a candidate enters the novelty archive once it clears a small competence floor (min_acc_for_novelty, default 0.05) and is sufficiently sparse. Parents are chosen by tournament selection or, with configurable probability, by sampling a MAP-Elites quality-diversity archive whose cells are binned by a depth proxy (min(9, nodes//3)) and a combined statefulness-plus-edge-density proxy (min(9, (stateful + edges//5)//2)); each cell keeps only its highest-scoring occupant. After a child is inserted, the oldest individual in the population is always evicted (the regularized-evolution 'kill oldest' rule) to keep the population churning rather than freezing on an early winner. The default run is small and continuous - population 10, 40 steps - and can instead be driven by random-search or an RL-controller mode through the same evaluation pipeline.
Self-expanding search space
EDAG expands its own vocabulary as it runs. As genomes are evaluated they are appended to a history, and every macro_mine_every steps the system mines that history for structure that recurs: mine_macros counts 2-, 3-, and 4-edge chains of node types and tallies which memory update rules appear most often, then promotes the most common ones into a MacroLibrary as either subgraph macros or memory-rule macros. During reproduction a child may, with probability 0.10, have a sampled macro spliced in - a subgraph macro merges the recorded nodes and edges (with id remapping) into the child, while a memory-rule macro rewrites the update_rule of one of the child's existing memory cells. Longer, more specific chains are promoted preferentially.
This is the code-level realization of the specification's 'composite mechanism' idea: substructures and state-update behaviors that repeatedly appear in good models are abstracted into first-class building blocks that future architectures reuse directly, so earlier discoveries become primitives for later ones and the search space grows as the run proceeds.
What it produces
A run outputs a Markdown report and a set of artifacts: per-checkpoint statistics (best accuracy and loss, node and edge counts, quality-diversity archive size, number of promoted macros), rendered diagrams of the best genome at the start, middle, and end of the run to show how it grew, the best genome as JSON with its weights, and TorchScript (optionally ONNX) export so the discovered model leaves the search as a deployable artifact. A JSON-Lines history logs one event per birth - its step, identifier, both parents, the operator that produced it, and its fitness, novelty, and score - so the lineage of any final model can be traced back through its ancestors to a seed, and the run's configuration is written alongside it.
The production entry point sweeps a spread of modalities - MNIST, KMNIST, FashionMNIST, SVHN, STL10, and the small TinyText and TinyGraph tasks - to exercise the convolutional, sequence, and graph execution paths of the compiler. The engine is implemented twice, in Python over PyTorch and in Rust over tch-rs against a common, deterministic evaluation pipeline, with a batched evaluation order and a seeded generator that keep the two aligned.
Abstract
EDAG is an evolutionary neural-architecture-search system whose unit of search is a learning mechanism rather than a scalar over a fixed menu of blocks: it discovers architectures that carry persistent state, update it over time, and compute in ways their designers did not specify. Each candidate is a genome encoded as a directed graph (a networkx DiGraph) of typed nodes, where edges carry one of three kinds: feed-forward (ff), state, or recurrent. Validity is defined on the feed-forward subgraph alone - it must be a DAG containing at least one input-to-output path - while state and recurrent edges are free to form cycles, because they are executed across timesteps rather than within a single forward pass, and it is through those cycles that memory and recurrence are expressed. A compiler, DynamicGenomeModel, turns any valid genome into a runnable PyTorch module by topologically sorting the ff subgraph and instantiating one module per node across eighteen node types inside a shared internal latent dimension (default 32); it selects a convolutional, sequence, graph, or flat-vector execution mode from the node types present and routes the input through the matching adapter. Memory-cell nodes maintain a persistent hidden buffer under a selectable update rule - a Linear+Tanh update, an EMA, or a GRU-style gate - recurrent edges feed the previous step's node outputs back in, and whether state is written during evaluation is a configurable toggle. The search is a steady-state, regularized (age-based, kill-oldest) evolutionary loop that selects on fitness plus a behavioral-novelty bonus and draws parents both by size-three tournament and by sampling a MAP-Elites quality-diversity archive binned on depth and statefulness; children are produced by graph crossover, macro insertion, weight inheritance from the primary parent, and a weighted set of mutation operators that include structural edits and two mechanism operators that inject memory cells (with explicit read and write edges) and recurrent feedback. A behavioral descriptor read from the run - the mean and standard deviation of the output logits, the norm of a single parameter update, and the change in memory state - places each candidate in the archive, novelty is the sparseness of a candidate among its neighbors, and evaluation is staged so that every child trains briefly first and only candidates that clear a competence gate earn deeper training. Every twenty-five evaluations the system mines recurring two-, three-, and four-node chains and common memory update rules from the genomes it has seen and promotes them into a macro library that later children splice in, so the operator set expands as the run proceeds. The engine is implemented in Python over PyTorch and in Rust over tch-rs against a common deterministic evaluation pipeline, runs over MNIST, KMNIST, FashionMNIST, SVHN, STL-10, CIFAR-10, and two checked-in tiny text and graph datasets, and emits for every run a metrics report with a rendered genome, a JSON-Lines lineage of every birth, the best genome and its weights, and a TorchScript (optionally ONNX) export.